 Jun Lee
Why Your AI Demand Letter Keeps Getting the Numbers Wrong
Why Your AI Demand Letter Keeps Getting the Numbers Wrong
AI demand letter tools get figures wrong because language models predict numbers rather than look them up. Here is why, and the process that catches it.
"It keeps getting the numbers wrong." That's the complaint we hear most from firms that tried an AI demand letter tool before finding a more deliberate approach.
A bill total is off by a few hundred dollars. A treatment date is a week early. A provider name is almost right, but not quite.
None of it is random, and none of it is a bug you can fix with a better prompt. It's how the technology generates numbers in the first place. This post explains the mechanism, because understanding it is the only way to build a workflow that catches it.
AI Doesn't Calculate. It Predicts.
Here's the part that surprises most attorneys. A language model doesn't look up a number and report it back. It generates text one token at a time, predicting what's statistically likely to come next.
For ordinary prose, that works remarkably well. Grammar, phrasing and sentence structure are highly predictable, so the model's guess is usually right.
Numbers are a different problem. A specific dollar figure, an exact date or a precise dosage needs accurate retrieval, not a plausible guess. And retrieval is exactly what a next-token predictor is weakest at.
The model isn't trying to recall "$4,827.50" from your client's file. It's predicting what number is likely to follow the words before it. Those are very different operations, and only one of them is reliable.
| Generating prose | Generating a specific figure | |
|---|---|---|
| What the model is doing | Predicting plausible phrasing | Predicting a plausible-looking number |
| Why it usually works | Grammar and structure are highly patterned | The exact value is not derivable from pattern alone |
| Failure mode | Awkward phrasing (easy to spot) | A confident, wrong number (hard to spot) |
Is This Proven, or Just a Theory?
It's in the research. OpenAI researchers argue that language models hallucinate because training and evaluation reward guessing over admitting uncertainty. A separate study found that models' accuracy on numerical tasks tracks how often the numbers involved appeared in their training data.
The first is "Why Language Models Hallucinate" (Kalai et al., 2025). Its point is that hallucination isn't a mysterious glitch a future update will simply remove. It follows from how models are trained and scored.
The second is Razeghi et al. (2022). On some tasks, models were more than 70 percentage points more accurate on the 10% most frequent terms than on the 10% least frequent. Your client's exact bill total is about as rare as a number gets.
A general-purpose chatbot isn't failing to calculate your client's medical bills. It was never calculating them in the first place. It was predicting what a plausible total might look like.
Why Does This Hit Demand Letters So Hard?
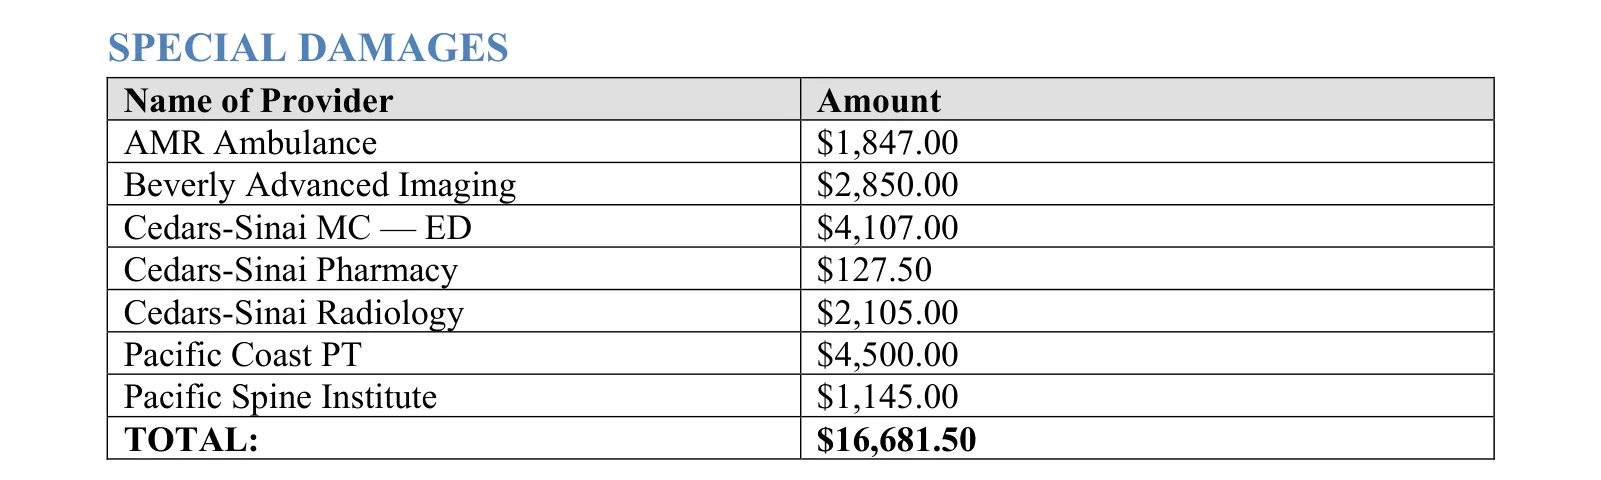
A demand letter is dense with exactly what these models handle worst: dollar figures for every bill, dates for every visit, provider names, policy numbers and diagnostic codes. A wrong number sits inside a financial argument. An adjuster who catches one has every reason to distrust the rest.
A typical legal-research hallucination is a misremembered case citation. A demand letter hallucination is a wrong figure in the specials table.
Can a Better Prompt Fix Wrong Numbers?
No. You can tell a model to double-check the math, and it may even write that it did, but the instruction doesn't change how it generates text. It's still predicting tokens, now including the phrase "I have verified this figure," which is its own kind of plausible-sounding fabrication.
Prompting your way around the problem doesn't work the way people hope. The fix has to change the process, not the wording of the request.
What Actually Reduces the Error Rate?
Change what the model is asked to do at each step. Extract every figure and date from the records first, as structured data. Then draft from that data, check the draft in a separate step, and show the reviewer which page each number came from.
| Approach | What the model does | Where a wrong number gets caught |
|---|---|---|
| One-pass drafting | Writes the prose and the numbers together | Only if someone rereads the whole file |
| One pass, better prompt | Same, plus a sentence saying it checked | Same as above |
| Extract, draft, validate | Pulls figures out as data, drafts from them, checks the draft separately | In the validation step, and at the source page |
Structured extraction before drafting
Don't ask a model to write a letter and produce the numbers as it goes. Extract every figure, date and fact from the source records first, as a structured dataset. Then the letter is written from that data, not invented alongside it.
A separate validation step
Drafting and checking shouldn't be the same pass. Writing persuasively and checking facts against source documents are different jobs.
Combine them in one step and an invented number slips through. The system that wrote the sentence has no independent way to catch its own error.
Traceability, not just confidence
The most useful signal a tool can give you isn't "this is accurate." That claim is exactly as unverifiable as the number itself.
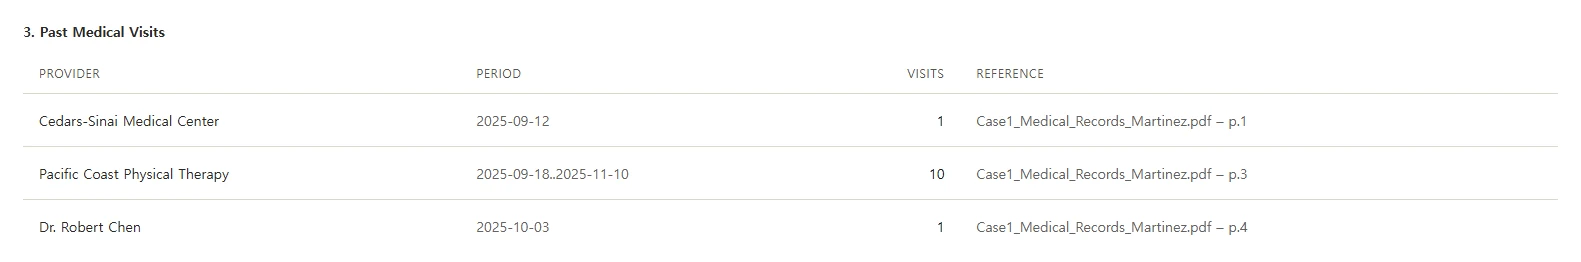
The useful signal is which page of which document a figure came from. Then a person can confirm it in seconds instead of rereading the file.
The Verification Habit That Actually Catches Errors
Whatever tool your firm uses, this is the discipline that catches a wrong number before it reaches an adjuster. Our free personal injury demand letter template shows where each of these figures sits in the letter.
The Honest Bottom Line
No current AI architecture, including ours, eliminates the tendency to generate a confident, wrong number. That's why Lexyno's AI demand letter drafts carry a source reference on each figure, so your paralegal can check it against the record.
What separates a usable tool from a liability is the workflow around that tendency. Either it's built to catch it, with structured extraction, separate validation and traceability your paralegal can act on quickly, or the product just hopes a good prompt is enough. It isn't.
The fix was never going to be a smarter sentence. It's a smarter process around the sentence.
Frequently asked questions
Language models generate text by predicting the next likely token, not by performing calculation or lookup. For prose, that works well because grammar and phrasing are highly predictable. Numbers, dates, and exact figures are different — they require precise retrieval, not pattern completion, which is exactly the operation these models are structurally weakest at.
Better prompting reduces some errors but cannot eliminate them, because the underlying limitation is architectural, not a matter of instruction. OpenAI researchers argue that models hallucinate because training and evaluation reward guessing over admitting uncertainty, so it is not simply an engineering flaw to be prompted away.
It is a property of how large language models generate text in general, not a flaw unique to any one product. The difference between tools is not whether this tendency exists, but whether the product is engineered to catch it before the number reaches the page — through structured extraction and a separate validation step against the source documents.
Every dollar figure, date, and provider name should be traceable back to a specific page in the source medical records, not just plausible-sounding. The fastest verification workflow is one where the tool shows you where each fact came from, so checking a number against its source takes seconds instead of re-reading the whole file.
Models will continue to improve, and tools built with structured fact-extraction and validation already reduce errors substantially compared to asking a general chatbot to draft from scratch. But no current architecture eliminates the underlying tendency entirely, which is why verification against source documents should remain part of the workflow regardless of which tool a firm uses.
Related posts
Legal Document Management Software: Security for PI Records
How to choose legal document management software for a PI firm: the security checks that matter for medical records, and where records leak instead.
Personal Injury Case Management Software: How to Choose
How to choose personal injury case management software: test deadlines, records, liens and settlement money on a closed file before you sign.
AI Policies for Law Firms: A Framework PI Firms Can Use
AI policies for law firms, built for PI practice: the eight sections a policy needs, sample wording, and the bar duties each section answers.
What's next?
Ready to see the difference in your next case?
Put these strategies to work. Try a mock demand generated by Lexyno today.
Request Evaluation Access